
AI fairness is often framed as a compliance issue.

This paper ( https://lnkd.in/d8WjCjPG ) makes a more useful point: in high-stakes systems, fairness should be engineered as a core design principle, not audited as an afterthought.
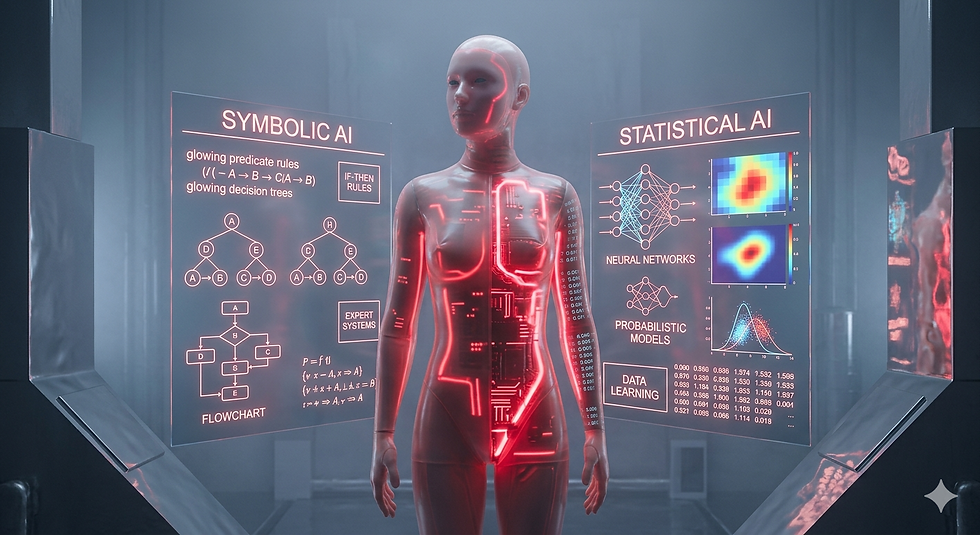
The authors show that counterfactual fairness can be embedded directly into a neurosymbolic framework, making the model’s behavior more transparent, testable, and easier to govern. That matters because leadership teams do not just need models that perform well — they need systems they can trust, explain, and defend.
What I find most important is the shift in mindset. Instead of treating fairness as a post-processing adjustment, the paper treats it as part of the learning architecture itself. That is the right direction for any AI deployed in recruitment, finance, healthcare, or other decisions where trust is non-negotiable.
The broader lesson is clear:
"as AI moves into more consequential decisions, the advantage will not belong to the fastest teams alone. It will belong to the teams that can combine performance, interpretability, and accountability in one system."
Comments